Transportation & Logistics AI

CVAT Data Annotation Solutions for Transportation and Logistics

Turn warehouse, yard, terminal, and roadside camera footage into model-ready datasets for inventory tracking, freight handling, fleet safety, and traffic monitoring.
Need to keep your data in your own infrastructure? Explore CVAT Enterprise
APPLICATIONS
Build high-quality training data for logistics AI tasks
Create labeled datasets for inventory tracking, freight handling, safety monitoring, and traffic analysis across warehouse, yard, in-cab, and roadside footage.
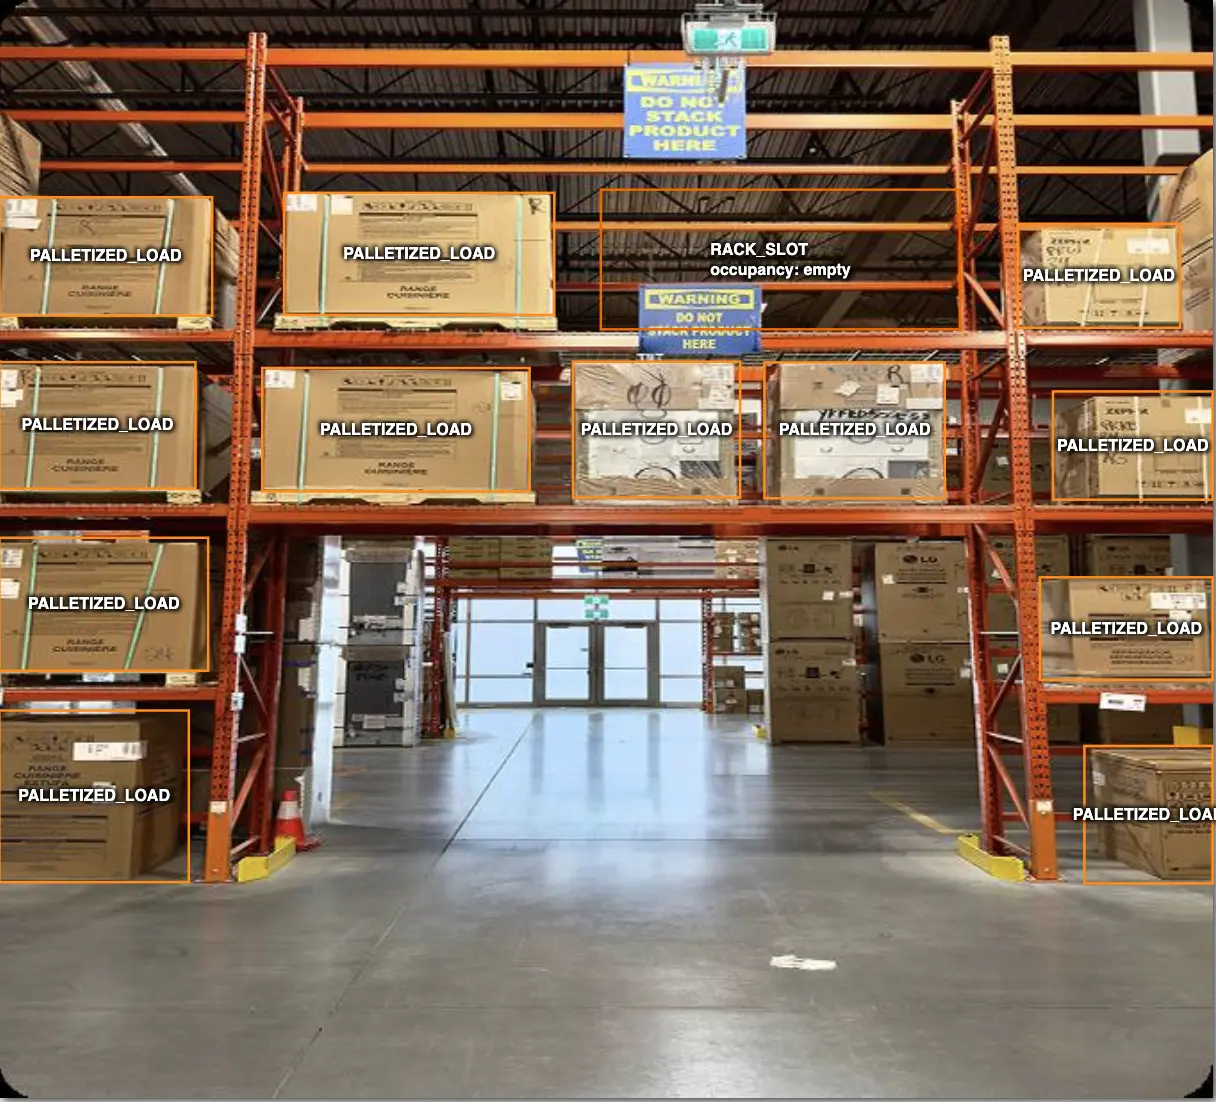
Warehouse inventory and pallet tracking
Detect and count pallets, cartons, containers, and stock locations to automate inventory checks and cycle counting.
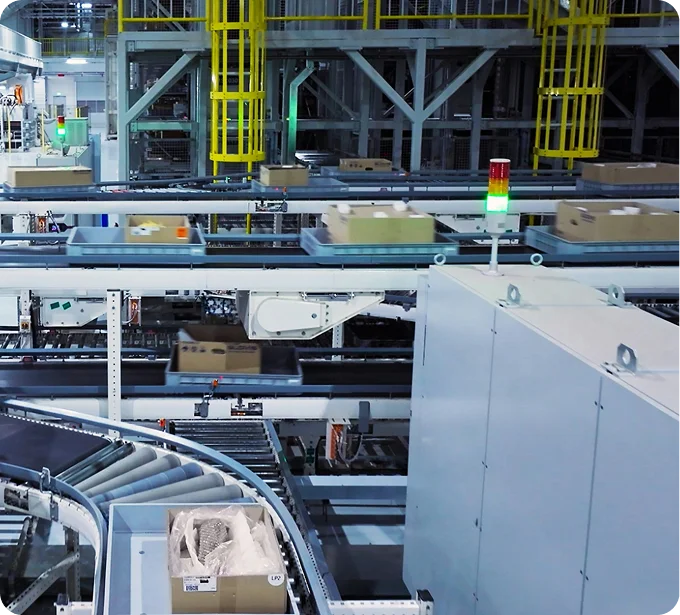
Parcel and package sorting
Label parcels, shipping labels, barcodes, and damage on conveyor and sortation lines for automated handling and exception detection.
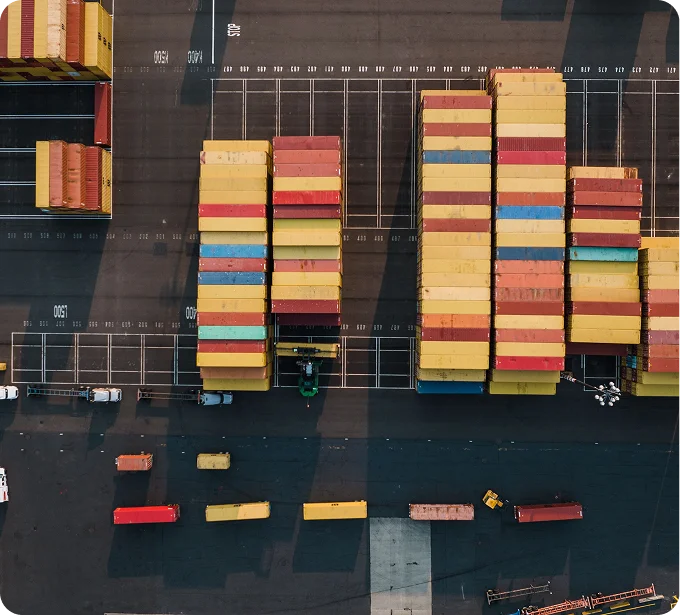
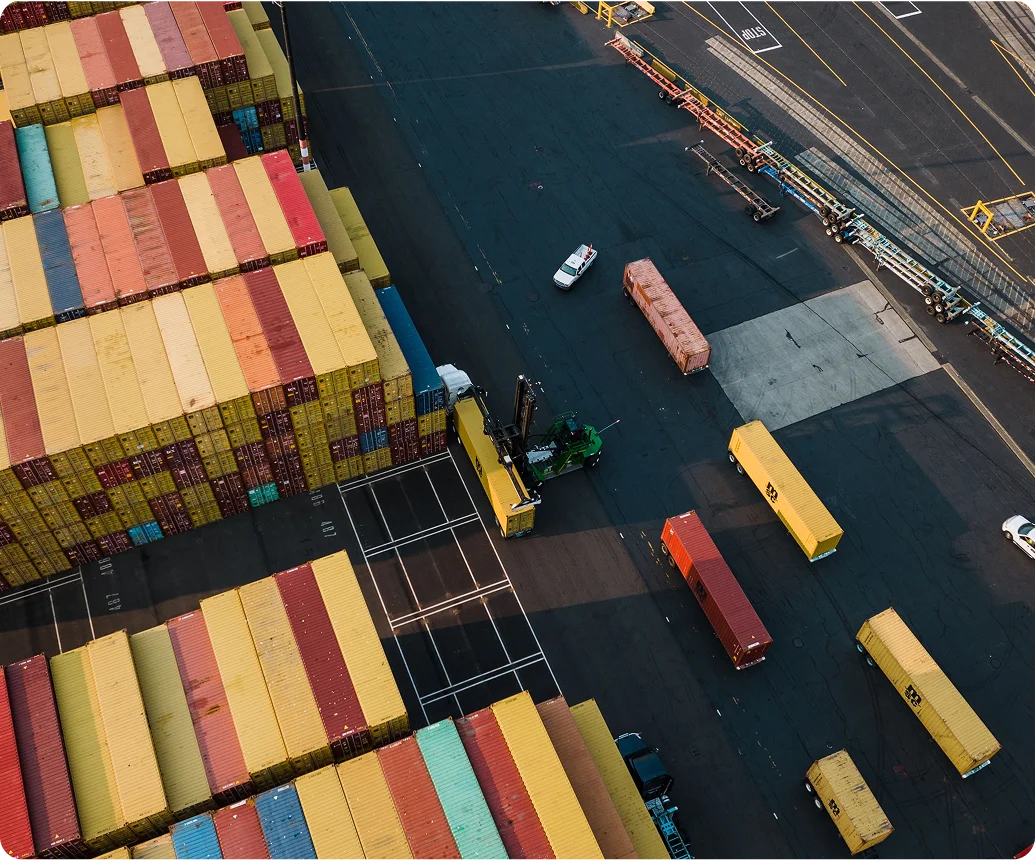
Yard, dock, and terminal operations
Annotate trucks, trailers, containers, and loading positions to measure yard occupancy, dwell time, and dock utilisation.
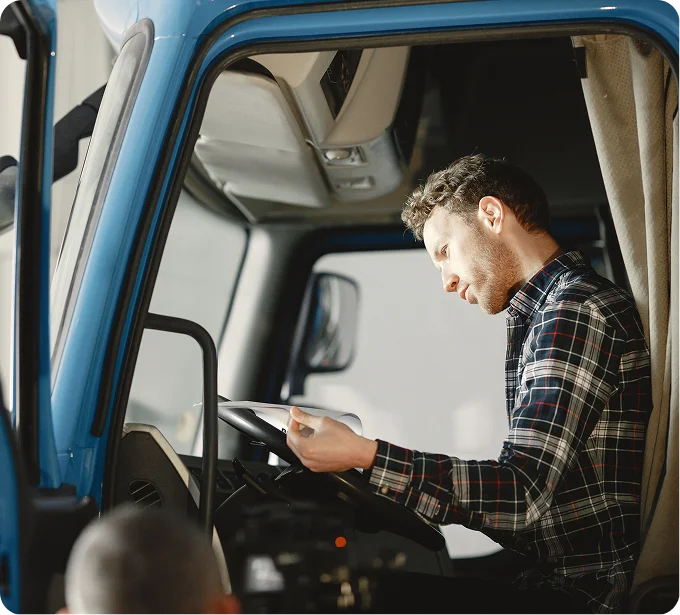
Fleet safety and driver behaviour
Label in-cab and outward-facing footage for distraction, following distance, and near-miss events across a fleet.
Traffic and roadside monitoring
Classify vehicles, count flow, and detect incidents in roadside and intersection footage for traffic management systems.
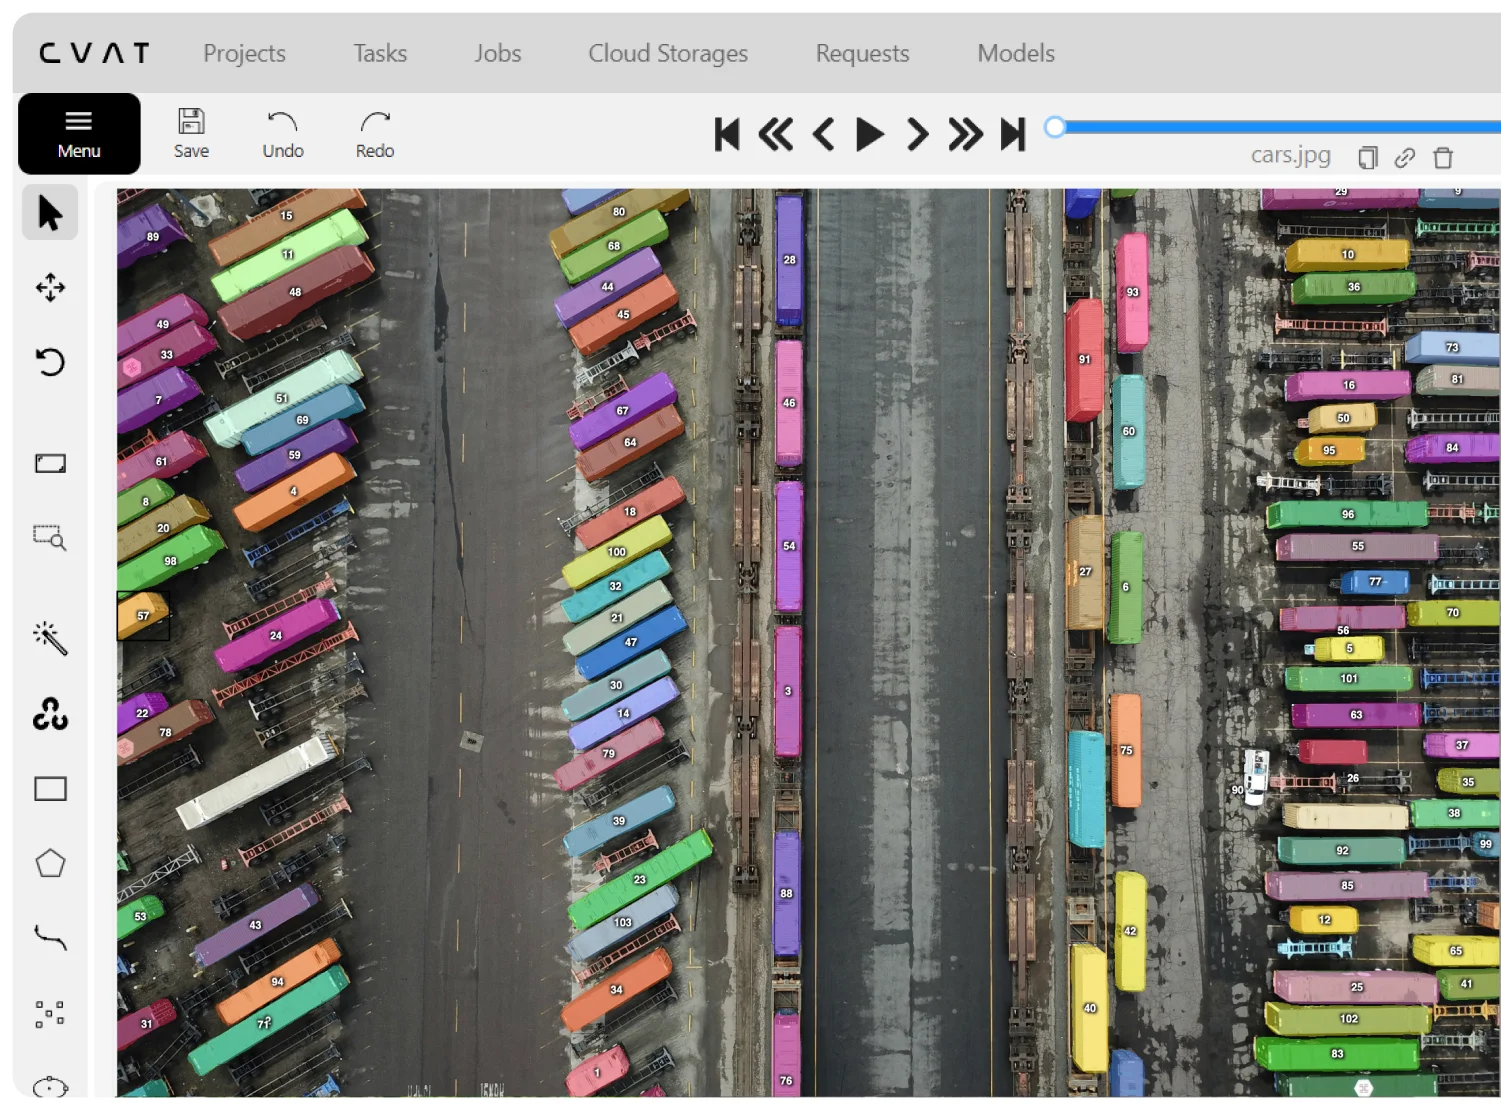
Rail and port asset monitoring
Annotate railcars, containers, cranes, and identification markings for automated asset tracking and condition checks.
CVAT PLATFORM

Manage the full logistics annotation workflow in CVAT

Import warehouse, yard, in-cab, and roadside video, annotate objects and events, coordinate multi-stage review, and export model-ready datasets from one workspace.

1. Import data from local files and cloud storage

Upload local datasets and existing annotations
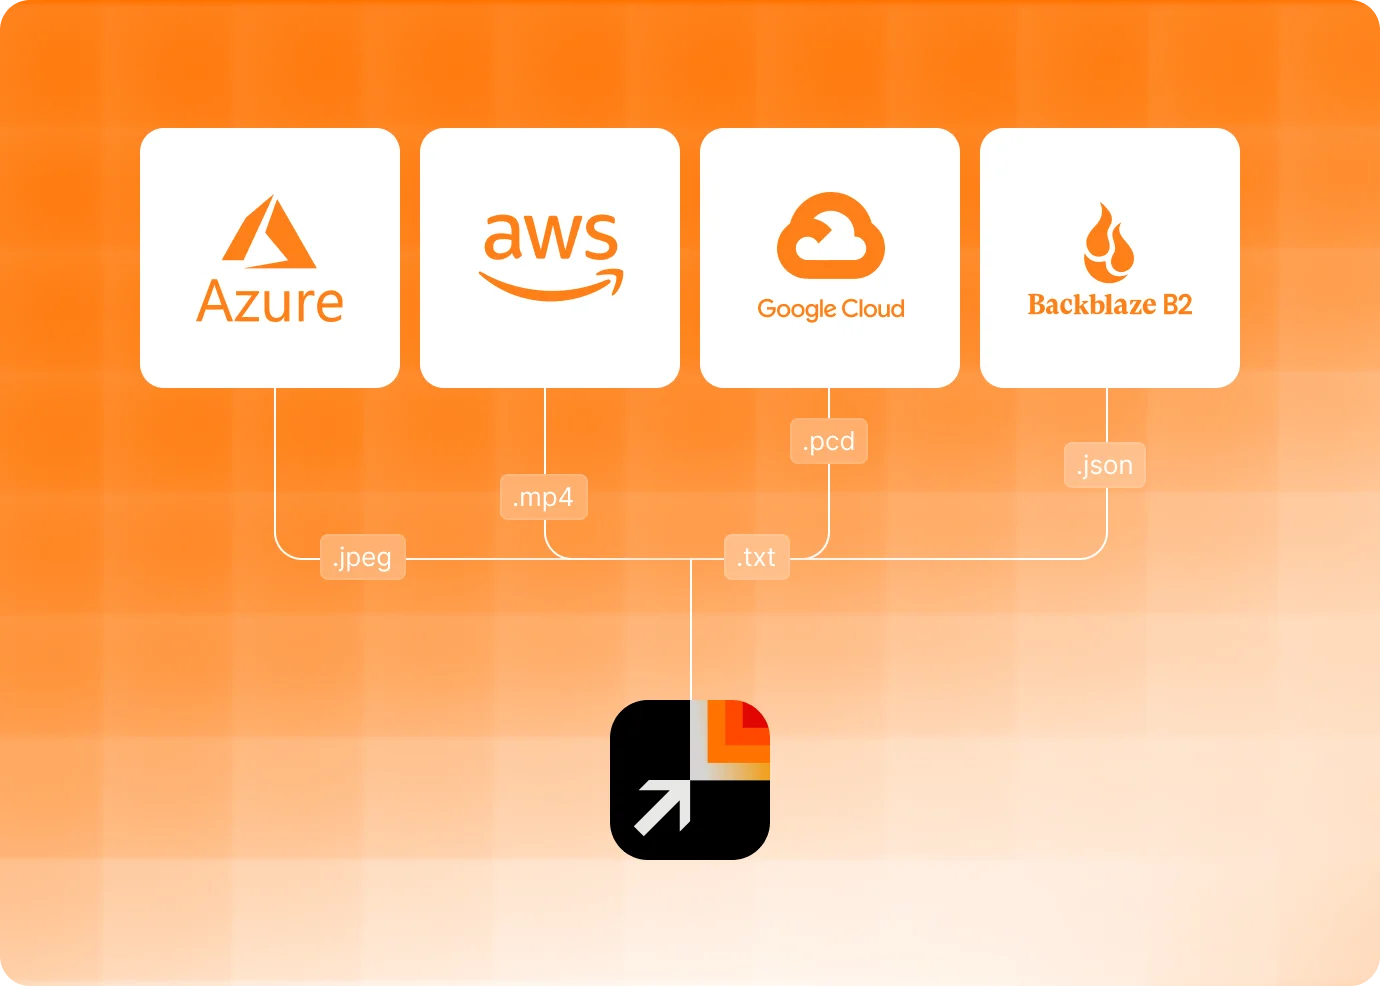
Connect Amazon S3, Azure Blob Storage, Google Cloud Storage, and other storages
Use S3-compatible buckets or self-hosted storage

2. Manage projects, tasks, jobs, and team access

Organize annotation work into projects, tasks, and jobs
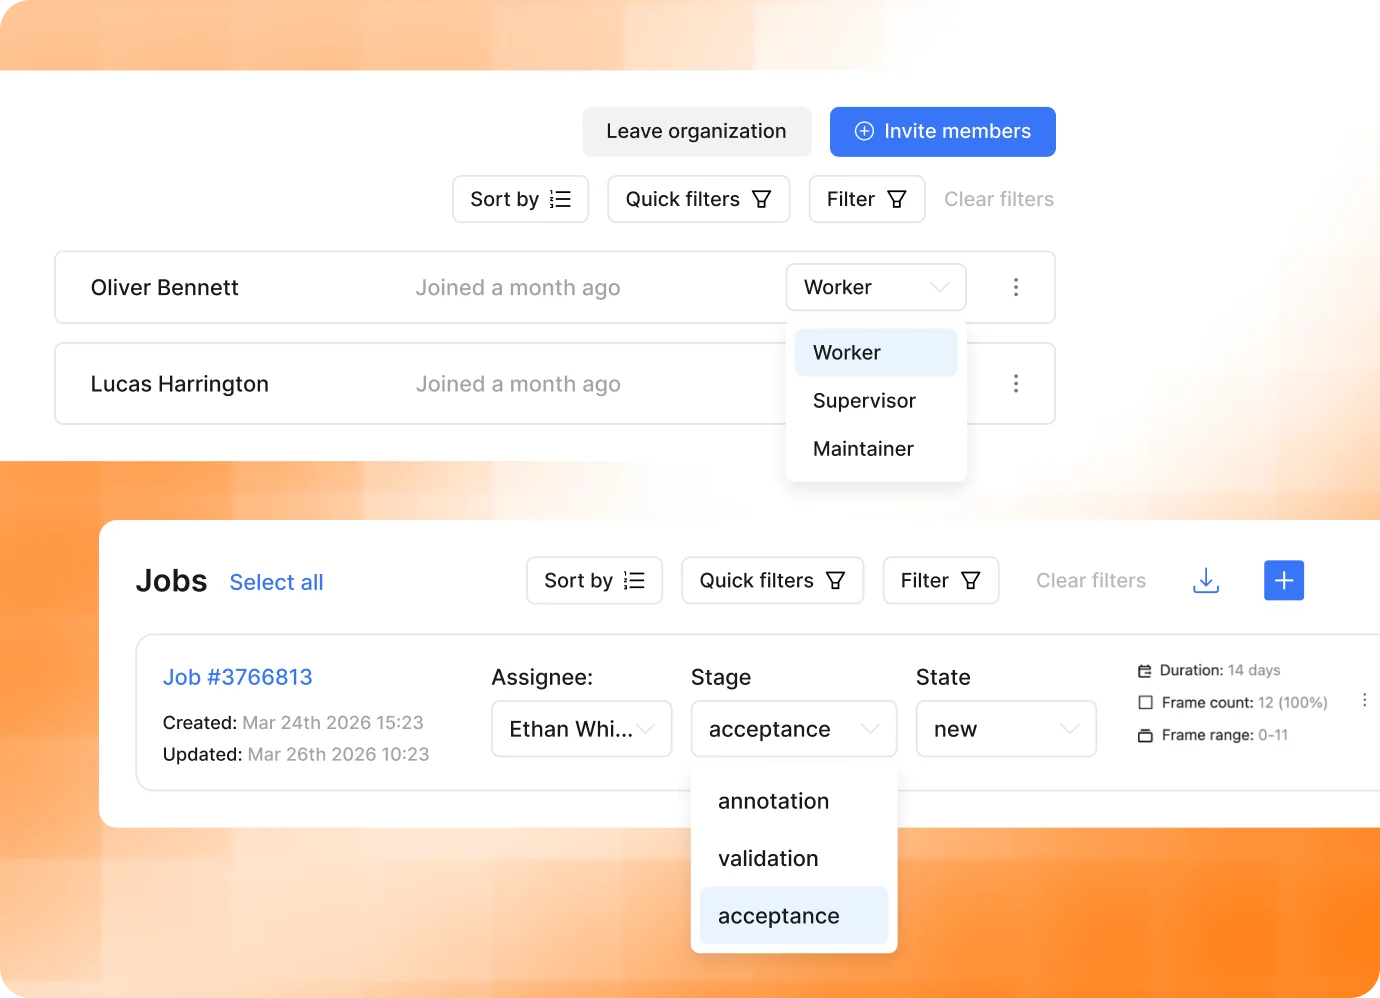
Assign annotators, reviewers, and project contributors
Manage roles, permissions, stages, statuses, and task ownership

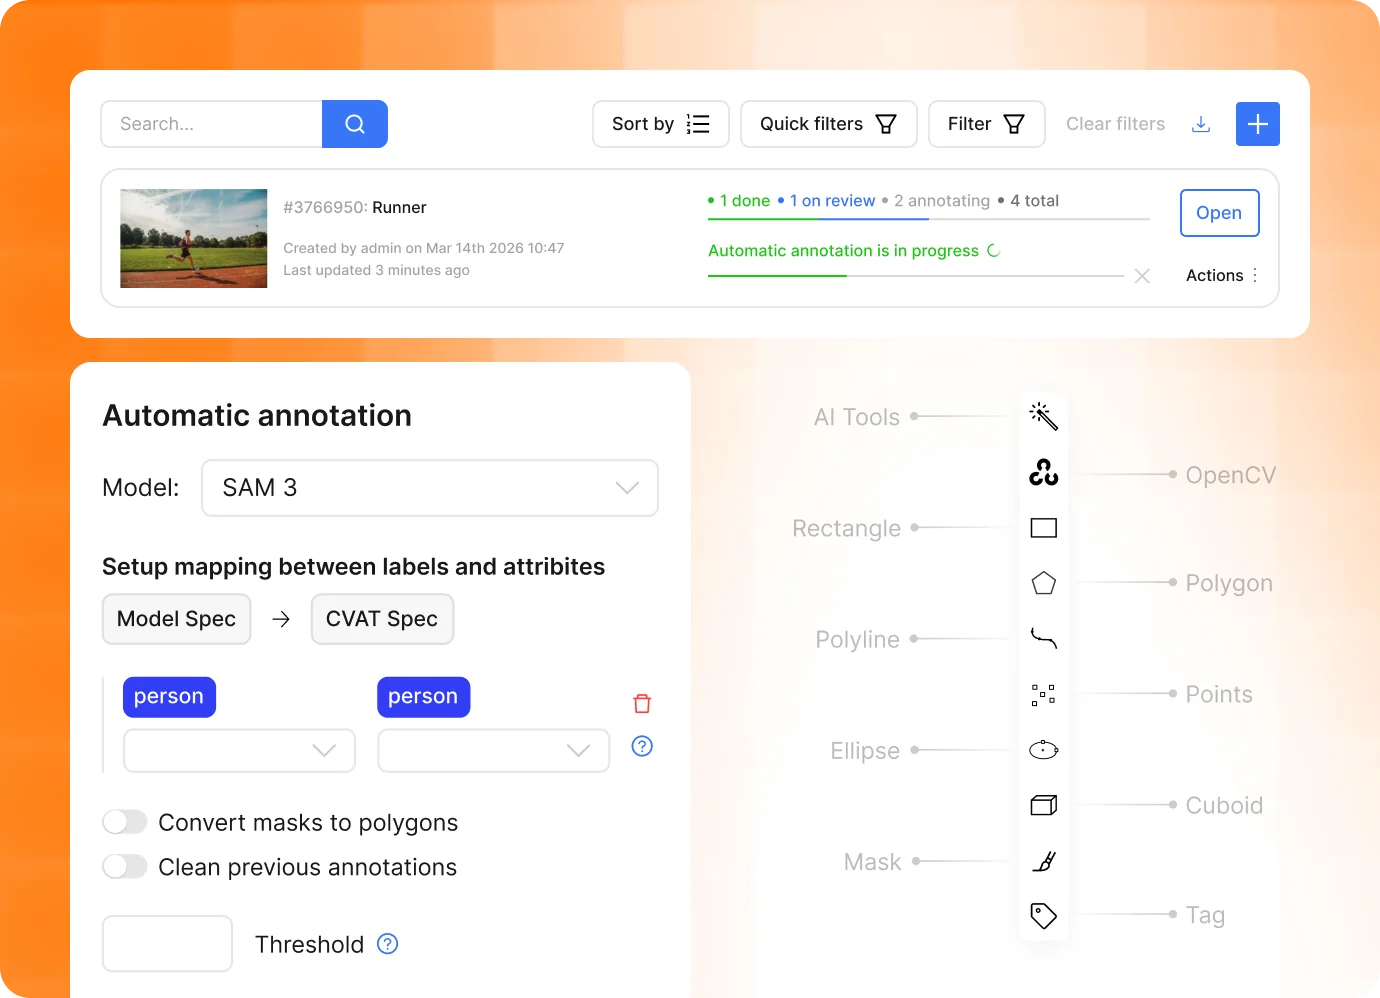
3. Label data with manual and automated tools

Create boxes, polygons, masks, skeletons, tags, and tracks
Speed up labeling with SAM 2, SAM 3, Ultralytics, Hugging Face models, or custom models
Support detection, segmentation, tracking, pose estimation, and other CV workflows

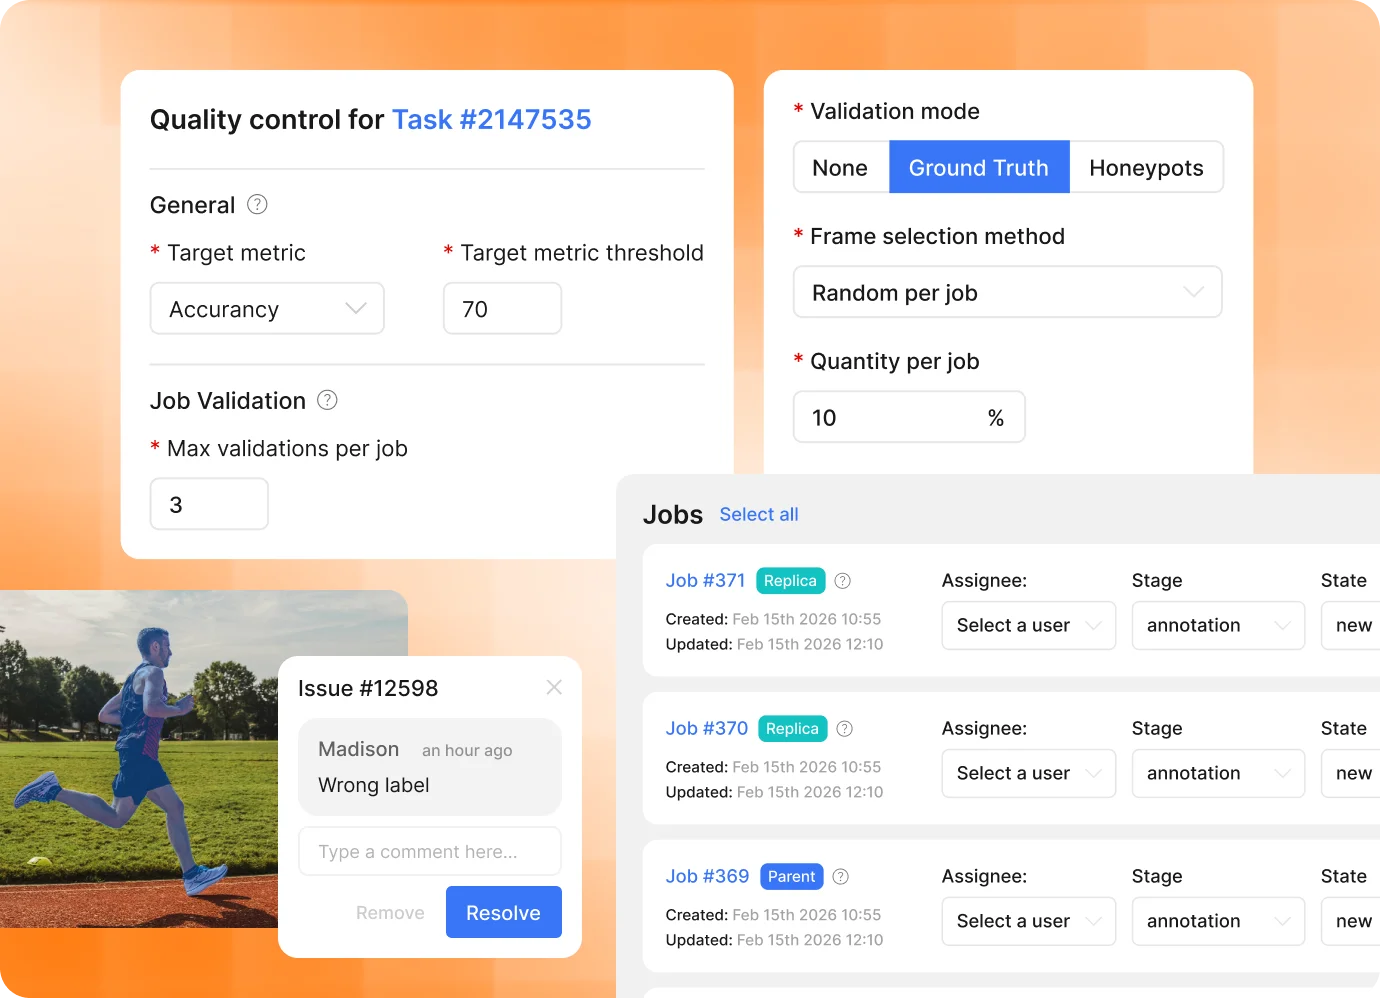
4. Validate annotations and control quality

Review jobs through validation and acceptance stages
Measure quality with ground truth, honeypots, and consensus workflows
Resolve issues and keep quality decisions traceable

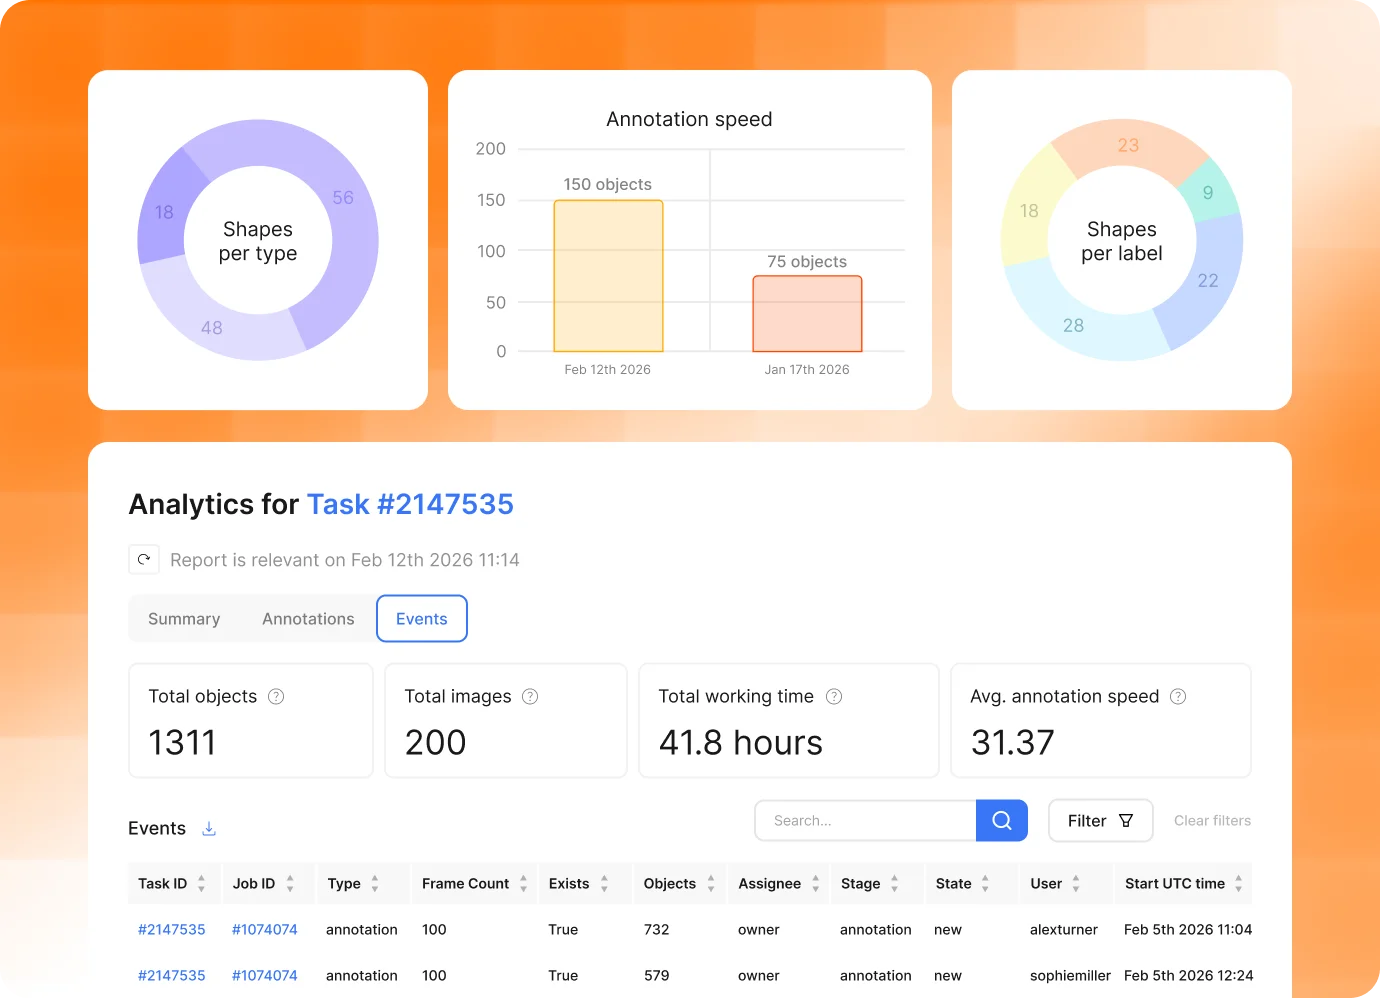
5. Monitor task progress and team workload

Track progress across projects, tasks, and jobs
Monitor team workload and completion status
Identify bottlenecks and measure annotation and validation throughput

6. Export datasets and integrate CVAT workflows

Export data in 20+ formats, including COCO, YOLO, KITTI, Cityscapes, and Pascal VOC
Automate import, task management, and export through API, SDK, and CLI
Build custom integrations around CVAT data labeling and ML workflows
CVAT LABELING SERVICES
Have CVAT deliver your logistics training dataset
Provide your site footage, object taxonomy, annotation guidelines, and quality requirements. Our project managers, annotators, and validators handle setup, labeling, review, and final delivery.
300+ dedicated annotators across 12 time zones
Real-time progress dashboards and delivery tracking
Scales from 1,000 to 100M+ labels without you hiring a single person
Multi-stage QA with rework guarantees and accuracy benchmarks
WHY CVAT
Why choose CVAT for logistics data annotation?
Track objects across busy sites, control where operational footage is processed, and scale across facilities and seasonal peaks.
Reliable tracking in dense scenes
Track pallets, containers, vehicles, and workers across long recordings with consistent identities, keyframe interpolation, oriented boxes, and structured attributes.
Keep operational footage in your environment
Use CVAT Online, deploy CVAT Enterprise in your infrastructure, or build on the open-source Community edition when yard, dock, in-cab, or worker footage carries privacy or contractual restrictions.
Scale across sites and peak volumes
Add CVAT Labeling Services as new facilities, camera angles, or seasonal volumes increase without moving to a separate annotation system.
CUSTOMER REVIEWS
Why AI teams choose CVAT for labeling their data
4.5/5

At e2m, we use CVAT to review computer vision detections of animals in massive camera trap image datasets. We found CVAT to be the best tool at this scale, enabling efficient image review and robust quality control.

Joshua Wilson

Senior Computational Ecologist

tbmaestro uses CVAT as a key tool to structure large-scale annotations for equipment detection on our inspection photos and to accelerate computer vision deployment in asset management.

Anthony Renard

AI Engineer

Our mission is to make vessels safer for every crew at sea. CVAT plays a critical role in that, helping us transform raw CCTV footage from maritime environments into the training data for our AI detection systems. From identifying unsafe behaviour to surfacing near-miss situations before they escalate, CVAT is the foundation that makes our safety intelligence possible.

Vladimir Ponomarev

CEO

CVAT helps us label sports images to build high-quality ground truth that enables our AI to analyze volleyball performance and provide personalized feedback. It gives us the flexibility to combine automated and human labeling, and makes it easier to test different models and refine the best approach for our AI.

Fabian van Schevikhoven

Founder

At Arboair, we annotate forestry imagery to deliver world-class tree analysis worldwide, and CVAT has been key to making that possible at scale. Its ease of use and flexibility across annotation use cases support our full workflow, from production models to experimental projects.

Jacob Hjalmarsson

COO

Vimaan uses CVAT as its primary data annotation tool and selected this tool after a thorough evaluation of alternative tools both in open source and closed domain. Top 3PLs and warehouses have improved their inventory accuracy, reduced mis-shipments, improved bin utilization, while reducing overall resource.

Sudhir Kumar Singh

CTO & Chief AI Scientist

Frequently Asked Questions

What types of logistics data can I annotate in CVAT?
CVAT can be used with fixed-camera and CCTV video, in-cab footage, conveyor and sortation line capture, and still imagery in supported formats. Teams commonly use it to build training data for inventory counting, freight handling, safety monitoring, and traffic analysis.
Can objects be tracked and counted across long recordings?
Yes. Track mode propagates an object across frames and interpolates between keyframes, keeping a consistent identity for the length of the recording. This is what makes reliable counting possible, since double counting and identity switches are the usual failure mode in dense scenes.
Can we capture container or vehicle identifiers alongside the object?
Yes. Object attributes let you record container numbers, licence plates, SKU references, condition, or status as structured fields on the same annotation, so one pass produces both detection and identification training data.
Which annotation types suit warehouse and terminal footage?
Pallets, cartons, containers, and vehicles are usually oriented boxes, since stacked and angled freight rarely sits square to the camera. Storage zones, travel lanes, and dock areas are polygons or masks. Worker pose for safety models uses skeletons and points. Condition and status are attributes on the object rather than separate classes.
Can we pre-label site footage with an existing detector?
Yes. Import predictions or connect a compatible custom model to generate a first pass across a full recording, then have annotators confirm, correct, or reject. Dense warehouse scenes benefit more than most, because the same objects repeat frame after frame.
Can CVAT pull footage directly from our camera storage?
CVAT supports connected cloud storage including Amazon S3, Azure Blob Storage, Google Cloud Storage, and Backblaze B2, so recordings can be annotated from wherever the camera network already writes them.
How do you avoid double counting in dense scenes?
Counting errors come from broken tracks far more often than from missed detections. Track mode holds one identity across frames, and review stages plus ground-truth jobs surface the fragments and merges that inflate a total. It is worth deciding in the guidelines what counts as one object when freight is stacked or partly out of frame.
Can one taxonomy cover cameras at different sites?
Yes. Labels and attributes are defined at project level, so every site, camera angle, and shift annotates against the same schema. That matters more here than in most domains, because a model trained on one facility’s camera geometry usually degrades on the next one.
Can CVAT Labeling Services take on a multi-site programme?
Yes. The service covers project setup, workforce allocation, annotation, review, quality control, and delivery against your taxonomy and acceptance criteria — which suits rollouts where each new facility, camera angle, and SKU range adds volume faster than an internal team can absorb it.
Can operational footage stay inside our own environment?
CVAT Enterprise supports private-cloud and on-premises deployment, which is normally what operators need when yard, dock, and in-cab footage carries worker, customer, or contractual restrictions.

Build your next

logistics dataset

with CVAT

Manage annotation with your own team or have CVAT deliver a validated dataset for your model.
Free plan available • No credit card required • GDPR & CCPA compliant
Try CVAT Online
PRODUCT
CVAT CommunityCVAT OnlineCVAT Enterprise
SERVICES
Labeling ServicesAudio Annotation Services
COMPANY
AboutCareersContact usLinkedinYoutubeGitHub
PRICING
CVAT OnlineCVAT Enterprise
SOLUTIONS
AutomotiveGeospatialInfrastructureLogistics
RESOURCES
All ResourcesBlogDocsCase StudiesChangelogAcademyFeature HighlightsPlaybooksTutorials
COMMUNITY
DiscordGitHub
Beyond Vision: CVAT Goes Multimodal and Introduces Audio Annotation.Learn more ➔