On August 25, 2026, Amazon posted a short notice on the Mechanical Turk homepage. After an internal assessment, the company decided to close Amazon Mechanical Turk (MTurk), and the marketplace will permanently shut down on September 30, 2026.
That notice gave requesters and workers about five weeks to wrap up and ended a 21-year run. Researchers used MTurk for surveys and data collection, businesses used it for content moderation and categorization, and machine learning teams used it to draw bounding boxes and verify labels, including the crowdsourced labeling behind ImageNet.
The closure did not come out of nowhere. In its June 30 service availability update, AWS moved Mechanical Turk into maintenance and stopped accepting new customers on July 30. Amazon has not shared a specific reason for the full shutdown.
So, what should teams that still depend on MTurk do now? Move to another crowd platform, manage their own annotation workforce, or hand the work to a professional labeling service?
The answer depends on the work itself. Human data labeling is not going away, but the type of human work that modern AI projects need is changing, and that change should decide where your annotation work goes next.
If you only have a minute, these are the points that matter most for your labeling pipeline:
- Amazon Mechanical Turk closes permanently on September 30, 2026, and the MTurk workforce option disappears from SageMaker Ground Truth and Amazon Augmented AI on the same day.
- SageMaker Ground Truth is not shutting down yet. It closed to new customers on July 30 and now runs in maintenance mode.
- MTurk worker panels, qualifications, and integrations do not transfer, so any migration is a workflow rebuild.
- Crowdsourcing still fits simple, independent, non-sensitive tasks that you can validate automatically.
- Complex, sensitive, or evolving projects are better served by a managed labeling service with measurable QA.
Key MTurk Shutdown Dates to Plan Around
The shutdown has unfolded in stages since June. These are the dates AWS and Amazon have published so far.
What Amazon Is Closing (and What It Is Not)
Some early coverage of the shutdown blurred the lines between several AWS products. A few articles even report that SageMaker Ground Truth closes on September 30. Before you plan a migration, it helps to separate what AWS has actually confirmed.
Services and Options That Are Ending
The MTurk marketplace. According to Amazon's closure FAQ, HIT submission ends on September 30, and any unsubmitted HITs expire automatically. Requesters can approve or reject submitted work and award bonuses until October 30, 2026, after which pending HITs auto-approve. Amazon expects to refund prepaid requester balances within 30 days, and transaction history stays available until January 28, 2027.
The MTurk workforce option in SageMaker Ground Truth and Amazon Augmented AI. The same FAQ states that the Mechanical Turk worker type will no longer be available when teams create labeling jobs or human review workflows as of September 30. If your Ground Truth jobs or A2I review loops route tasks to the public crowd, they need a different workforce before that date.
SageMaker Ground Truth Plus. AWS's managed labeling offering has already ended. According to the June 30 service availability update, it reached end of support on June 30, 2026.
Services That Keep Running for Existing Customers
SageMaker Ground Truth. The AWS Ground Truth documentation says the service closed to new customers on July 30, 2026, and that existing customers can keep using it as normal, with private or vendor workforces in place of the MTurk crowd. AWS says it will keep investing in security and availability but does not plan new features.
Amazon Augmented AI. A2I moved into maintenance alongside Ground Truth. It no longer accepts new customers, but it keeps running for existing ones without the MTurk workforce option.
Maintenance mode is not a shutdown. However, it is still a signal worth weighing if either service sits at the center of your long-term pipeline.
Why Replacing MTurk Takes More Than a New Worker Pool
Many teams think of MTurk as "the workers." In practice, years on the platform leave an entire operating layer behind: HIT templates, qualification tests, approval rules, bonus logic, and API scripts that push results into training pipelines.
Very little of that moves with you. Even Toloka, which built a dedicated MTurk migration page, states that MTurk worker panels and qualifications do not transfer and that existing API integrations need adapting. The same applies to any destination you pick.
Before you commit to a replacement, pressure-test the new setup against the questions that will decide whether it actually holds up in production. Here’s how you can do that:
- Which of your current tasks still suit a distributed crowd, and which have outgrown it?
- How will you select and qualify contributors without your existing qualification history?
- How will annotators receive instructions, examples, and rulings on new edge cases?
- What validation will catch errors, low-effort work, and disagreement, and who resolves it?
- How will you protect confidential, personal, or regulated data?
- How will finished annotations reach your training pipeline, and in what format?
- Who owns project management, rework, and delivery deadlines?
If most of those answers point back to your own engineers, you are not just swapping a worker pool. You are rebuilding a workflow and a quality control system.
How the Crowdsourced Data Labeling Market Is Changing & Why Your Decision Matters
MTurk's closure fits a broader pattern, with three developments showing where human data work is heading, and a fourth showing where the big platforms are stepping back.
Simple Text Microtasks Are Moving to Machines
A 2023 study in PNAS compared ChatGPT with MTurk crowd workers on text annotation tasks such as relevance, stance, topic, and frame detection. ChatGPT's zero-shot accuracy beat the crowd by about 25 percentage points on average, at a per-annotation cost roughly thirty times lower than MTurk.
That same year, researchers at EPFL reran a summarization task on MTurk and estimated that 33 to 46 percent of the crowd workers used large language models to complete it. For requesters, that finding raises an uncomfortable question. Is crowd data still human data?
Neither study says crowd work has no value, and the EPFL authors caution that their results may not generalize to other tasks. Together, though, they show the simplest text tasks under pressure from two sides: models can do the work directly, or quietly do it for the people being paid.
Remotasks and Outlier Point Toward Specialist Work
Remotasks, the contributor platform operated by Scale AI, built its name on image, video, and 3D sensor annotation, including LiDAR labeling for autonomous driving programs. When Scale launched Outlier for generative AI work, it transitioned Remotasks contributor accounts and generative AI tasks to the new platform.
Outlier looks very different from the original Remotasks. It recruits subject matter experts to provide expert human feedback for AI models, with contributors in fields such as mathematics, coding, law, and chemistry writing training data and evaluating model outputs.
Remotasks has not disappeared, but its footprint has narrowed since 2024. The direction is clear. The highest-value human work in that ecosystem now centers on expertise and model evaluation.
Toloka Shows Crowdsourcing is Evolving, Not Ending
Toloka remains an active crowdsourcing and human data provider, and it is openly courting teams that are leaving MTurk. Its relaunched self-service platform uses an AI agent to turn a plain-language task description into a structured project.
It matches work to contributor tiers that range from general annotators to AI training specialists and credentialed domain experts. It then checks each result against approved quality rules with LLM-based reviews and routes failing work back for revision.
That is a very different product from an open task marketplace. Modern crowd platforms now compete on contributor selection, workflow configuration, and automated QA, not just on the size of the crowd.
Hyperscalers Are Pulling Back While Demand Keeps Growing
The last development to note is that AWS is not alone in this move. Microsoft plans to retire Azure Machine Learning data labeling on the same date, September 30, 2026, a change we covered in our CVAT vs. Azure ML data labeling comparison.
Demand for labeled data, however, keeps climbing. Grand View Research projects that the global data collection and labeling market will reach $17.10 billion by 2030, growing 28.4% a year from 2025.
Our read is simple. Annotation work is not shrinking. It is moving away from cloud add-ons and open microtask marketplaces, toward dedicated annotation platforms, specialized providers, and tasks that require judgment and domain knowledge.
Where Crowdsourced Data Labeling Still Makes Sense
Even in the midst of all that change, crowdsourcing remains a practical choice for many projects. It works best when every item stands on its own, the instructions leave little room for interpretation, and the data carries no confidentiality risk.
Think of tasks with clearly right and wrong answers. Image classification, simple object verification ("Does this image contain a car?"), preference selection between two outputs, basic transcription, and straightforward data collection all fit this profile. So do projects where you can validate outputs automatically or through consensus, and projects that benefit from broad geographic or linguistic diversity.
One condition matters most. In most self-service setups, the customer still owns task design, contributor monitoring, and QA, so your team needs capacity for that work. Capabilities also vary by platform, so confirm support for your task type, data format, and quality checks before you migrate.
When Crowdsourcing Becomes a Poor Fit
On the other hand, there are examples where crowdsourcing is not a good fit.
Complex Geometry, Video, and 3D Data
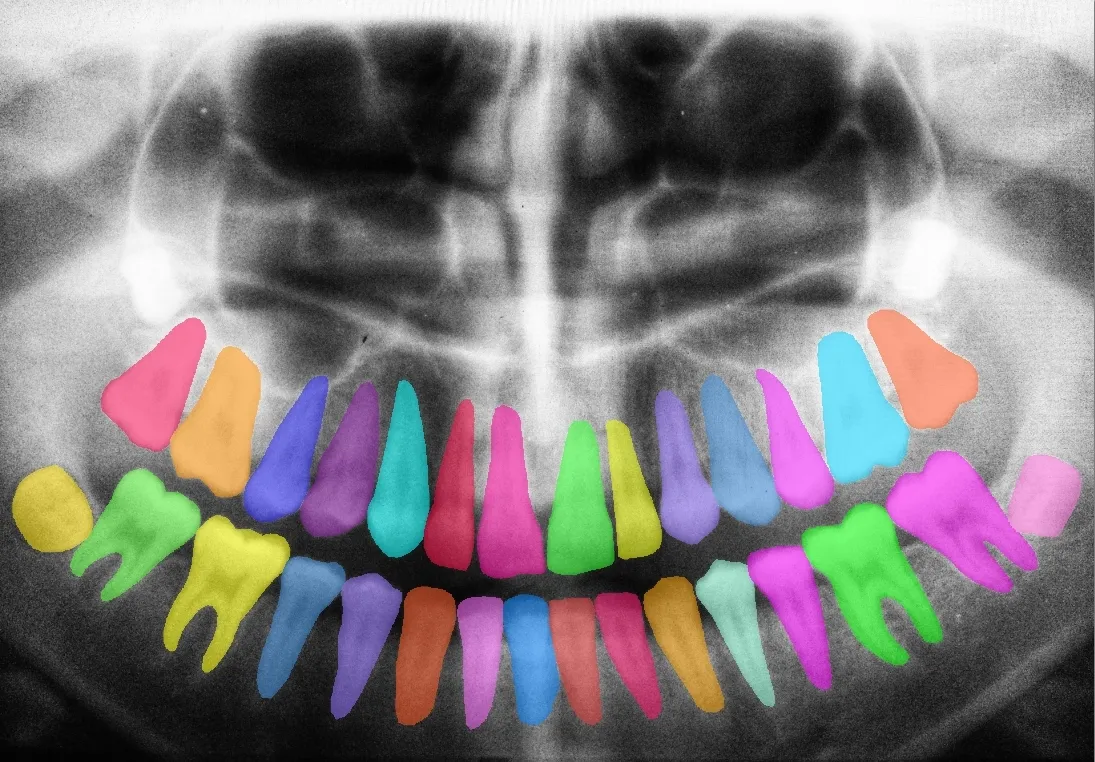
Precise polygons, instance masks, and keypoints demand trained hands and clear boundary rules. Video adds another layer, because each object must keep the same identity across hundreds of frames.
Split a sequence into independent microtasks, and those track IDs quickly break apart. 3D point clouds and multi-sensor data raise the bar again with specialized tools, cuboid conventions, and spatial reasoning that take time to learn.
Domain Expertise and Sensitive Data
Medical scans, scientific imagery, industrial defect data, and audio that requires linguistic knowledge all need annotators who understand the subject. Our look at medical data annotation shows how quickly domain errors turn into model errors.
Data sensitivity is just as important. Amazon's own FAQ states that MTurk, as a public crowd marketplace, is not designed for tasks that contain personal or sensitive data. Regulated or confidential datasets need NDAs, access controls, and clear accountability.
Our analysis of the Scale AI data leak shows what can happen when annotation environments are treated as "just labeling."
Evolving Guidelines and Quality You Cannot Auto-Check
Detailed ontologies with many attributes, subjective edge cases, and guidelines that change after each model experiment all call for a team that learns as the project moves.
The same goes for quality requirements that no simple automated rule can verify, and for delivery schedules that depend on predictable capacity rather than whoever happens to be online that week.
Crowdsourced vs. Professional Labeling Services at a Glance
The table below summarizes how the two models typically differ. Individual platforms and providers vary, so treat it as a starting point for your own evaluation.
What a Managed Labeling Service Adds Beyond Workforce Access
Most teams compare labeling options by price per task or price per object. That comparison misses where projects actually slow down.
Delays rarely come from a shortage of hands. They come from unanswered questions, guidelines that do not cover real data, quality nobody measured, and engineers pulled away from model work to manage it all.
A managed labeling service is built to absorb that work. You are not just renting annotator hours. You are handing off the coordination, training, review, and accountability that sit around the labeling itself. The value shows up most clearly in the problems it takes off your plate.
These are the operational problems a professional service is designed to solve, and how it solves each one:
- You are not sure the project is feasible. A proof of concept on a sample of your data shows expected quality, turnaround, and cost before you commit to full production.
- Your data needs context. The provider selects annotators for the project and trains them on your guidelines, your classes, and your edge cases, so you are not relying on whoever picks up the next task.
- Questions have nowhere to go. A dedicated project manager collects questions, sets priorities, and keeps delivery on track. Your team gets one point of contact instead of hundreds of anonymous contributors.
- Your guidelines keep breaking on new cases. The annotation team flags ambiguous examples as they appear, and both sides refine the guidelines together without relaunching the whole project.
- Nobody can define "good enough." A managed service agrees on measurable targets up front, then reports against them with metrics such as accuracy, precision, and recall. Our guide to annotation quality metrics explains how those numbers work.
- Your model team works in iterations. Batch deliveries let you train, evaluate, and send feedback while labeling continues.
- You cannot afford capacity gaps or security gaps. The provider owns workforce availability, and security requirements become part of both the contract and daily operations.
- Your team also stops managing contributor payments, rejection disputes, and daily annotation operations. If you are comparing vendors, our guide on how to choose a data annotation service provider walks through the questions to ask.
How CVAT Fills the Gaps MTurk Leaves Behind
MTurk gave teams two things: access to people and an API to route work to them. When it closes, most teams lose more than that. They lose the tooling they used to qualify contributors, the checks they used to validate results, and the pipeline that moved labels into training.
The good news is, there is an easy way to transition, as CVAT covers those gaps from both directions.
Already Have Annotators? Replace Your MTurk Workflow With the CVAT Platform
This path fits ML teams, research groups, and data operations leads who already work with employees or contractors and want direct control over their data, project configuration, roles and assignments, guidelines, and review workflows.
CVAT Online replaces the qualification and validation logic you built around MTurk with built-in quality controls, including Ground Truth jobs, honeypots, consensus workflows, and immediate job feedback. Our overview of annotation quality assurance shows how these layers fit together.
CVAT Enterprise adds fine-grained access control, and self-hosted or air-gapped deployment, so sensitive data never leaves your environment. Our guide to CVAT Online and Enterprise infrastructure compares both options in detail.
The MTurk shutdown also highlights a less obvious advantage. CVAT's core is open source on GitHub under the MIT license. If a vendor ever changes its terms or exits the market, your annotation platform stays available to you.
No Annotation Team? Let CVAT Labeling Services Run the Project
This path fits teams that need labeled data without building a labeling operation. CVAT provides and manages the workforce, annotator training, project management, annotation, review and QA, progress tracking, and delivery of finished annotations.
CVAT Labeling Services brings 300+ expert annotators across 12 time zones and more than 12 years of experience with computer vision and visual data. The team labels images, video, and 3D point clouds, and also provides audio annotation services.
All work happens inside CVAT itself, with no outsourcing layers between you and the people labeling your data. After delivery, you can keep maintaining or growing your dataset in the free CVAT Community edition.
Here’s How You Can Go From First Sample to Final Dataset With CVAT Labeling Services
On MTurk, a project often started the moment you published a batch. You found out whether your instructions worked after the results came back, and every fix meant another round of HITs. A managed project flips that order.
The questions that usually surface halfway through a crowd project, such as unclear class definitions, missed edge cases, and quality targets nobody wrote down, get answered before full production begins.
That upfront work is what keeps a project on schedule and on budget. You see real annotations on your own data before you commit, you know exactly what each delivery will contain, and you have one person accountable for getting it there.
Here is how a typical CVAT Labeling Services engagement unfolds, stage by stage:
- Share your data and requirements. You send a representative sample along with your goals, classes, and quality expectations.
- Review a free proof of concept. The CVAT team labels the sample under an agreed scope and guidelines, so you can judge quality, turnaround, and deliverables before committing.
- Refine the guidelines and quality targets. Together, we finalize annotation rules and define measurable KPIs such as accuracy or precision.
- Approve the proposal and delivery plan. You receive pricing, a delivery schedule, the batch structure, and the exact output formats.
- Start production with a trained team. CVAT assigns professional annotators to your project, and work typically begins within one to two business days of contract signing.
- Track progress and share feedback. Your dedicated project manager sends regular updates, and you can review work in an isolated, role-based workspace.
- Pass layered QA. Expert review, cross-checking, and automated methods such as Ground Truth, honeypots, and consensus verify each stage, with QA reports that include a confusion matrix and key accuracy metrics.
- Receive your dataset in batches. CVAT delivers annotations in the agreed format, along with a QA summary and final project notes. Corrections follow the acceptance process agreed at the start.
All projects run under strict NDAs and follow GDPR and CCPA principles.
CVAT can also connect to your own AWS S3, Azure Blob, or Google Cloud storage, so your data does not have to leave your environment. Pricing is available per object, per image or video, or as a custom model, with a minimum project budget of $5,000.
Our article on annotation services pricing explains this all in more detail.
Frequently Asked Questions About the MTurk Shutdown
When does Amazon Mechanical Turk shut down?
Amazon Mechanical Turk closes permanently on September 30, 2026. HIT submission ends that day, and requesters can approve submitted work and award bonuses until October 30, 2026.
Is SageMaker Ground Truth shutting down too?
No AWS source says so. Ground Truth closed to new customers on July 30, 2026, and existing customers can keep using it with private or vendor workforces.
Only the MTurk workforce option inside Ground Truth ends on September 30. Ground Truth Plus, AWS's managed labeling offering, already reached end of support on June 30, 2026.
Why is Amazon closing Mechanical Turk?
Amazon has not given a specific reason. Its notice says only that the decision followed a regular assessment of its programs, tools, and services.
Can I move my MTurk workers and qualifications to another platform?
Generally, no. Worker panels and qualification history stay with MTurk.
You can reuse your instructions, examples, and acceptance criteria to set up a new project, but contributor selection and validation have to be rebuilt.
What is the best MTurk alternative for data labeling?
It depends on the task. Crowd platforms still suit simple, independent, non-sensitive work. Teams with their own annotators can move their workflow to a dedicated annotation platform such as CVAT.
Projects involving video, 3D data, domain expertise, sensitive data, or strict quality targets are usually better served by a managed service such as CVAT Labeling Services.
What should MTurk requesters do before September 30?
Export your HIT templates, qualification tests, results, and examples of accepted and rejected work, since MTurk removes HIT data after 120 days.
In that time you need to review pending submissions, verify your payment details for the balance refund, and switch any Ground Truth or A2I jobs that use the MTurk workforce to a private or vendor workforce.
Choosing the Right Workforce Model After MTurk
The end of MTurk is a good moment to match each labeling task with the right workforce model, instead of simply moving everything to the next marketplace.
Choose crowdsourcing when your work splits cleanly into clear, independent, easily validated tasks, the data is not sensitive, and your team has the time to manage task design and QA.
Choose professional labeling services when your project needs trained annotators, direct communication, controlled data handling, evolving guidelines, predictable capacity, or a quality outcome you can measure.
Many teams will end up using both, and that is fine. What matters is deciding now, before September 30th.
Ready to move your annotation work off MTurk? Discuss your labeling project with CVAT and start with a free proof of concept.
Already have an annotation team? Try CVAT Online for free, or explore CVAT Enterprise for self-hosted, security-first deployments.